




Skip to content

QA for AI agents

Your AI agent answers customers. Kaizo checks every answer.

Kaizo scores 100% of your AI agent conversations against your own scorecard, the same one your team is scored on, and links every score to the evidence in the conversation. Keep it fully automated, or add human review exactly where it matters.

Live in days · Native Zendesk and Salesforce apps

QA for AI agents
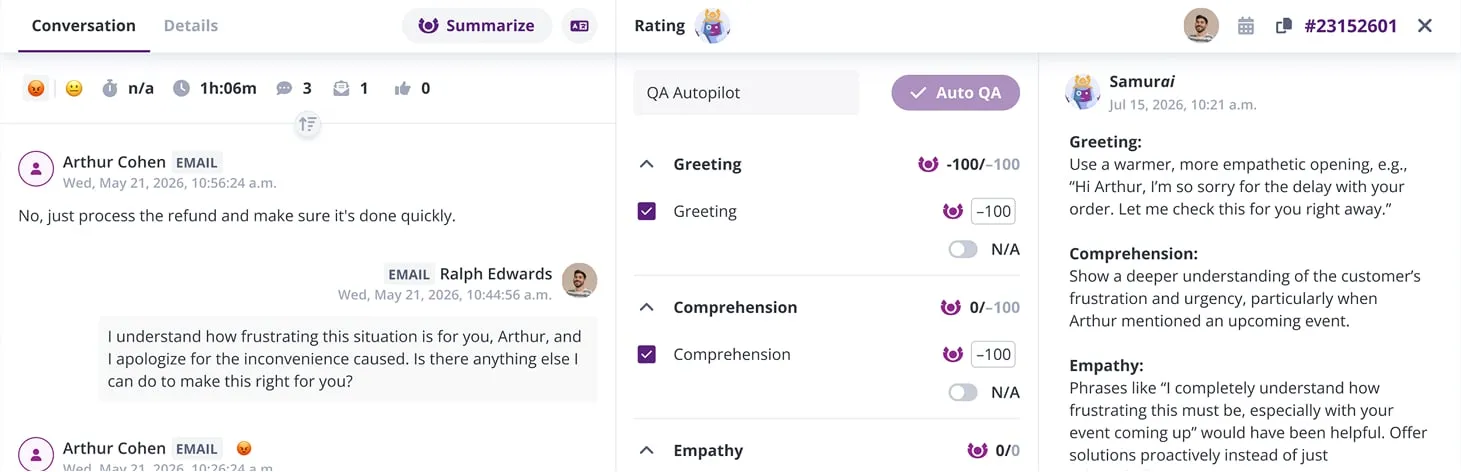
AutoPilot scoring a resolved support conversation against a custom scorecard

Trusted by global support teams

5/5 on G2
  • AICPA SOC 2 seal SOC 2 Type II
  • ISO 27001 mark ISO 27001
  • GDPR stars GDPR
Trust Center

An automated resolution is not a quality score

Your helpdesk counts a conversation as resolved when the customer did not reach a human. That does not tell you whether the answer was right. An AI agent can invent a policy, declare a false resolution or keep a case it should have handed over, and every dashboard still counts it as a win. Because it answers from the same prompt and content each time, the same mistake repeats across every conversation it touches, and a 2% sample will usually miss it.

How it works

One standard for human and AI agents

Kaizo runs inside the helpdesk where your AI agent's conversations already live, and scores them the way it scores your team's.

Your scorecard

The same scorecard, with checks built for a bot.

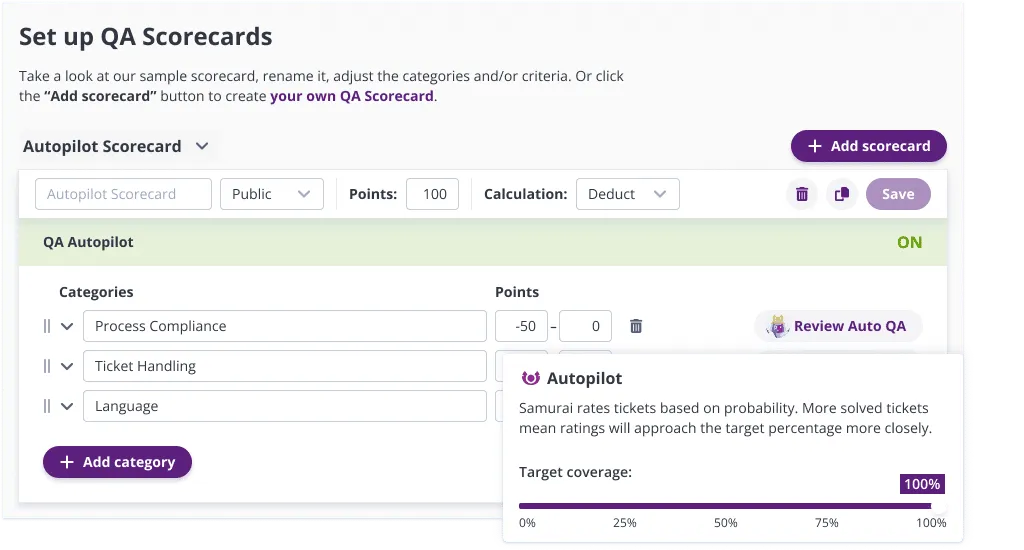
Score AI agent conversations on the same scorecard as your team's, so you can see how human and AI agents perform side by side. Then add the criteria where a bot fails: factual accuracy, policy fidelity, scope and escalation. Write them in your own words and connect your knowledge base, so the AI judges against your content.

  • Criteria in your own words, not a template
  • Shared criteria keep human and AI results comparable
  • Extra checks for invented facts and invented policy
How scorecards work
Your scorecard
A Kaizo QA scorecard with AutoPilot switched on at 100% target coverage

Every conversation

Every AI agent conversation scored, with the evidence.

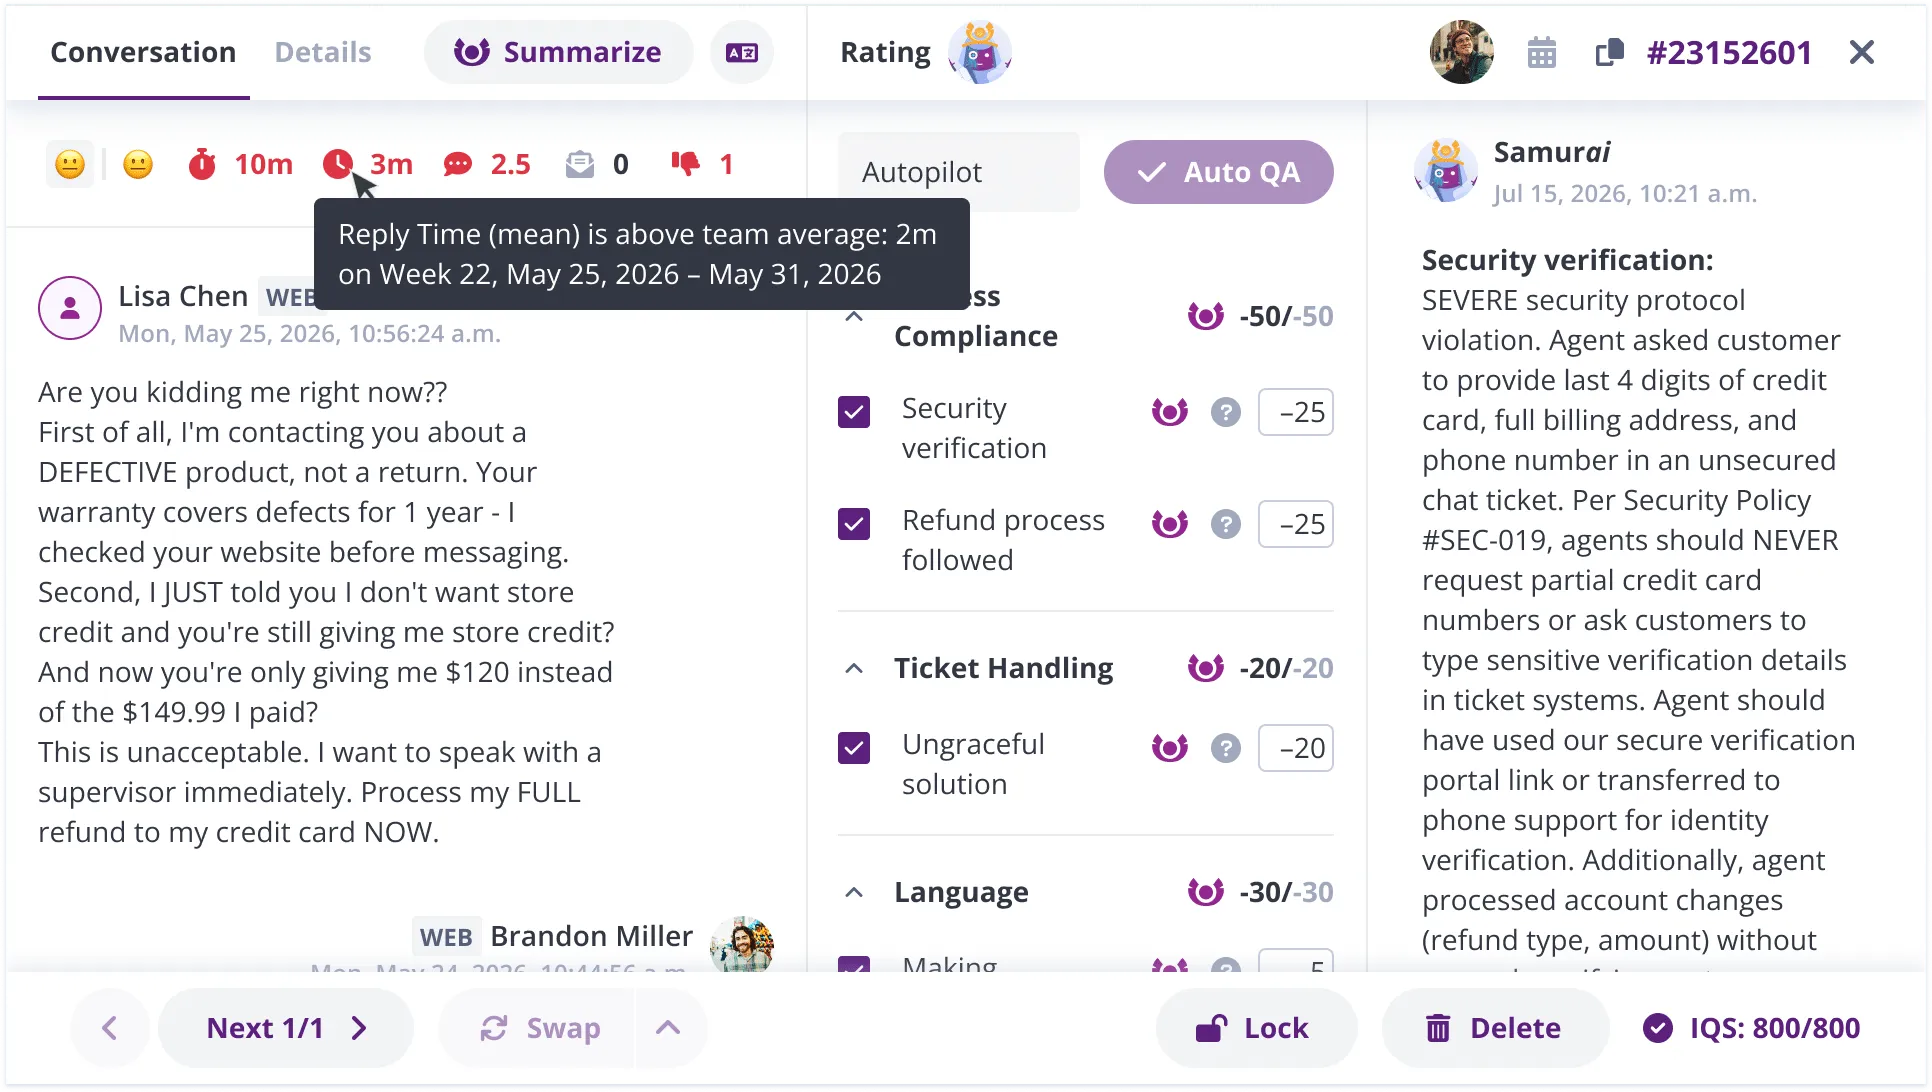
AutoPilot scores each conversation when it resolves and attaches a comment that explains the score. Every score links to the evidence in the conversation, so a failure becomes a specific example you can take to whoever owns the prompt or the help center article.

  • 100% of conversations, not a sample
  • Each score explained and linked to the lines behind it
  • Choose which queues, channels or teams it scores
More about AutoPilot
Every conversation
AutoPilot scores on a support conversation, with the reason for each failed criterion

Monitoring and analytics

See where the AI agent fails, and why.

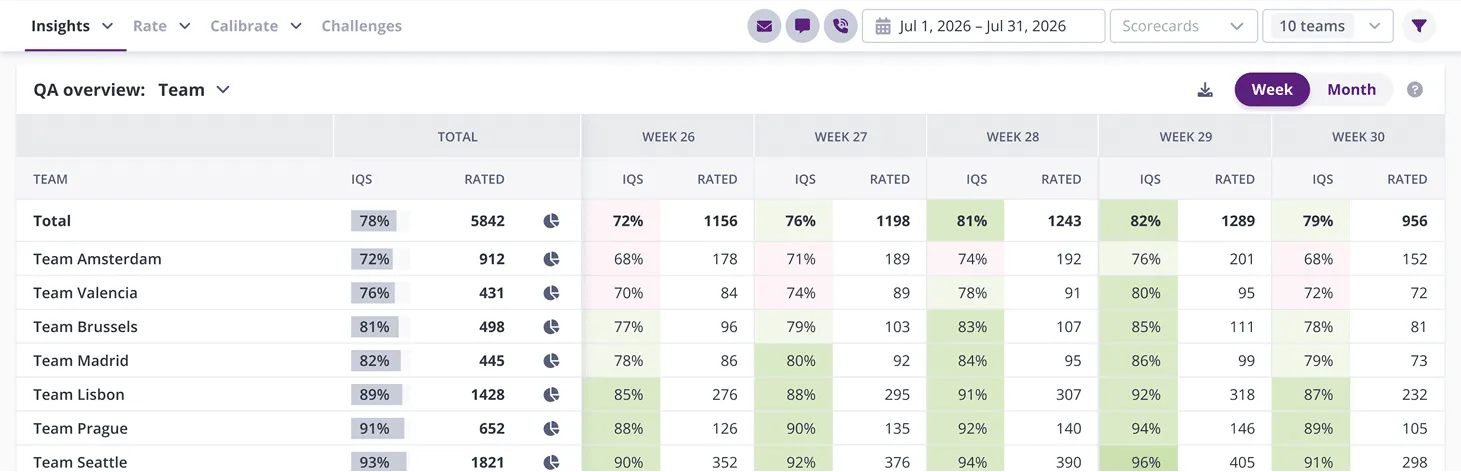
With every conversation scored, a recurring failure stops being an anecdote and becomes a trend you can track by team and by week. Root-cause analysis groups the failures behind a dip, so ten bad answers from one article become one fix. Re-score after each change to confirm the fix held.

More about root-cause analysis
Monitoring and analytics
Kaizo QA overview showing quality scores by team and by week

Human review

People stay in the loop.

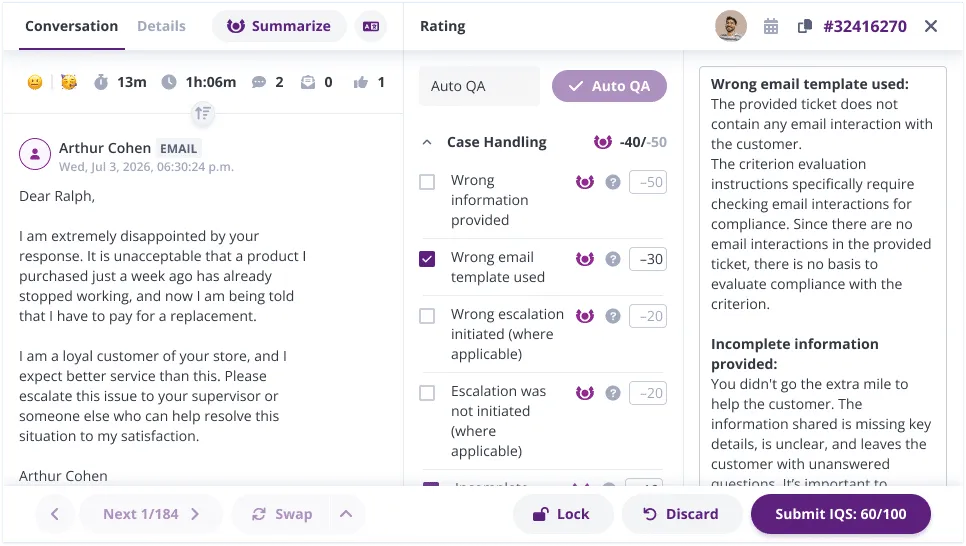
Test the scoring against your historical ratings before it goes live, and tune the criteria until it matches your team. Reviewers keep the conversations that need judgement: Auto QA pre-fills the criteria and drafts the feedback for them to edit and approve.

More about Auto QA
Human review
Auto QA pre-filling evaluation criteria for a human reviewer
100%
of QA automated at UiPath
200%
ROI on QA automation at UiPath
75%
less coaching prep at EverHelp

When Kaizo is not the right tool

Kaizo scores conversations once they have ended, in the helpdesk where they live. If what you need is a developer test suite before launch, such as prompt regression tests in your CI pipeline, that is a different stage and a different kind of tool, which can run alongside Kaizo. And if your AI agent handles a few dozen conversations a week, read them yourself: a weekly hour with the transcripts and a short checklist will find most problems.

New to this? Read our guide to QA for AI agents, why containment rate is not a quality score, which AI customer service metrics to track, or see pricing.

Testing a voice agent?

Testing a voice agent before launch, with scripted test calls, is pre-launch testing: a different stage from QA of live conversations. Talk to us about your setup and we will be straight about fit.

Support teams that stopped sampling

  • 50%

    less QA time

    “Our tickets can be long and complex. AI has been a life-saver in our experience.”

    SteelSeries

  • 75%

    faster resolution

    “Kaizo is an essential part of finding the root causes of areas we need to improve, then improving on that.”

    Foot Locker

FAQ

Frequently asked questions

What is AI agent QA?

AI agent QA means scoring the conversations your chatbot or AI agent handles against a written standard, so you know whether its answers were right and allowed, not only whether the customer reached a human. Kaizo does it on every conversation, with each score linked to the evidence.

Can Kaizo score AI agents from other vendors?

Yes. If the conversation is in Zendesk or Salesforce, Kaizo scores it on the same scorecard as your team's, whoever built the agent. In Zendesk, that includes the conversations Zendesk's AI agents handle.

Does the AI agent get the same scorecard as our people?

It can share the criteria that apply to both, such as a correct answer and the right tone, which keeps the results comparable. Then add the criteria where a bot fails: grounding in your own content, policy limits, scope and escalation.

Can Kaizo check the handoff from the AI agent to a human?

Yes, as criteria on your scorecard: did the AI agent escalate on the right trigger, did it pass on the context, and did the human agent pick it up. You see the handoff in the same conversation the score links to.

Does a high containment rate mean the AI agent is working?

Not on its own. Containment counts a conversation as a win when the customer did not reach a human, and a false resolution or a case the agent should have handed over looks exactly like that. You need to score what the agent said to know whether a contained conversation was a good one.

Who checks the scores?

Your team, wherever it matters. You test the scoring against your past ratings before it goes live, every score links to the evidence so anyone can check it, and Auto QA drafts feedback for a reviewer to edit and approve.

Do we need to change our helpdesk?

No. Kaizo integrates natively with Zendesk and Salesforce Service Cloud and reads conversations straight from them. Setup takes days, not a connector project.

Does Kaizo sell AI agents too?

Yes. The Kaizo Agentic Customer Service Platform brings role-based AI agents for the work behind support quality, running as a pilot in Q4 2026, and their work is measured to the same standard as your people's. The Quality Assurance Platform that scores AI agent conversations is available now.

See it on your AI agent's conversations

We will score a sample of your real AI agent conversations against your criteria and show you what the dashboard counted as a win.

Trusted by global support teams

  • Foot Locker
  • SteelSeries
  • Canva
  • GetYourGuide
  • Instacart